Prometheus metrics
If your team already runs Prometheus and Grafana, Warren adds what the broker's own metrics do not know: which queues hold dead letters, how close each node is to blocking publishers, which Warren alerts fire, and what operators replayed, discarded or parked.
Turn it on
Set a token and let Prometheus send it:
WARREN_PROMETHEUS_TOKEN=$(openssl rand -hex 24)scrape_configs:
- job_name: warren
metrics_path: /actuator/prometheus
authorization:
credentials: <the token>
static_configs:
- targets: ["warren:8080"]Without the token, or in Community, /actuator/prometheus answers 401 or 403: queue and host names are not for everyone who can reach the port. The values come from Warren's sampling, so they are as fresh as WARREN_METRICS_SAMPLE_INTERVAL (30 seconds).
What it exports
| Metric | Labels | Meaning |
|---|---|---|
warren_dlq_messages, warren_dlq_consumers | cluster, vhost, queue, kind | dead-letter and parking queues (kind is dead-letter or parking) |
warren_cluster_up | cluster, vhost | 1 when the last sample of the cluster entry worked |
warren_cluster_sampled_timestamp_seconds | cluster, vhost | when it was sampled |
warren_node_disk_headroom_bytes | broker, node | free disk above disk_free_limit; negative during a disk alarm |
warren_node_memory_used_ratio | broker, node | memory in use as a share of the high watermark |
warren_node_alarm | broker, node, resource | 1 while a disk or memory alarm blocks publishers |
warren_alerts_firing | rule, cluster, target, target_type | 1 per Warren alert that fires right now |
warren_actions_total | cluster, kind, status | finished replays, discards, purges, parks, exports and publishes |
warren_action_messages_total | cluster, kind, result | the messages they handled, succeeded or failed |
Plus the usual JVM and HTTP metrics of the Warren process.
Grafana dashboard
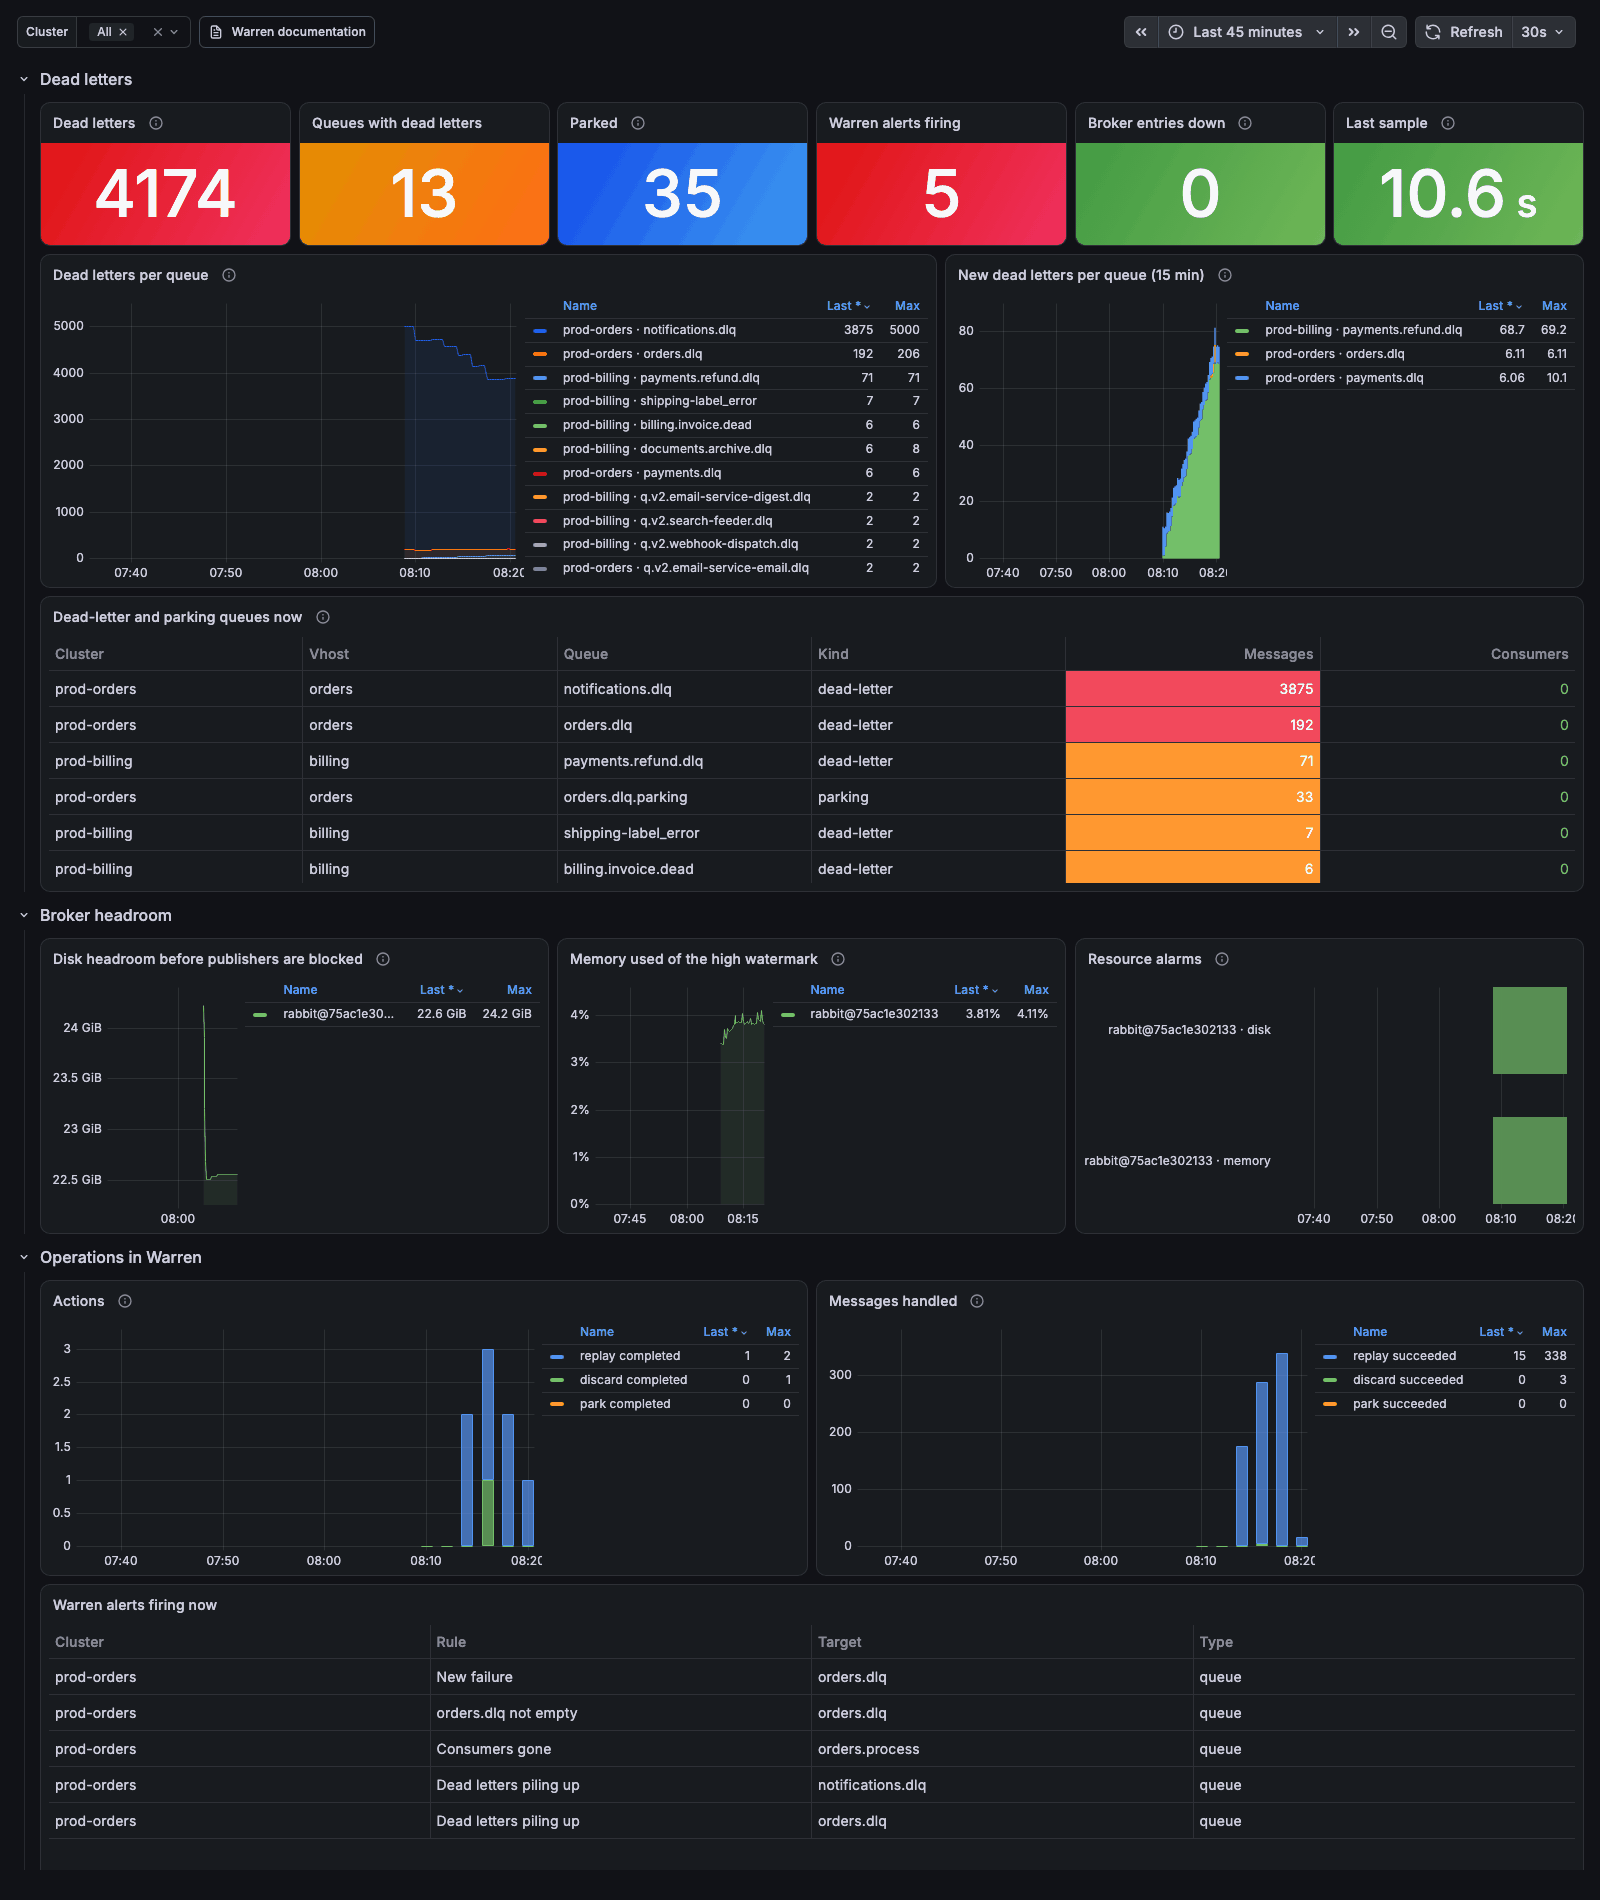
warren-dashboard.json (also on grafana.com) shows it all on one page: dead letters per queue and how fast they arrive, a table of every dead-letter and parking queue with its consumers, disk and memory headroom before RabbitMQ blocks publishers, resource alarms, the Warren alerts that fire, and the replays, discards and parks operators ran. In Grafana: Dashboards → New → Import, upload the file and pick the Prometheus that scrapes Warren. A cluster filter at the top narrows it to one or more cluster entries.
Ready-made alerting rules
warren-alerts.yml holds nine rules to start from: dead letters waiting or piling up, a dead-letter queue that something consumes, a broker Warren cannot read, sampling that stopped, under 1 GB before publishers are blocked, memory near the watermark, a resource alarm, and failed replays.
rule_files:
  - warren-alerts.yml
For example, the rule that warns before RabbitMQ blocks publishers:
- alert: WarrenBrokerDiskLow
  expr: warren_node_disk_headroom_bytes < 1e9
  for: 5m
  labels:
    severity: warning
Several Warren instances on one database? Scrape all of them: the gauges come from the instance that runs the monitoring loop, the counters from the instance that ran the action.